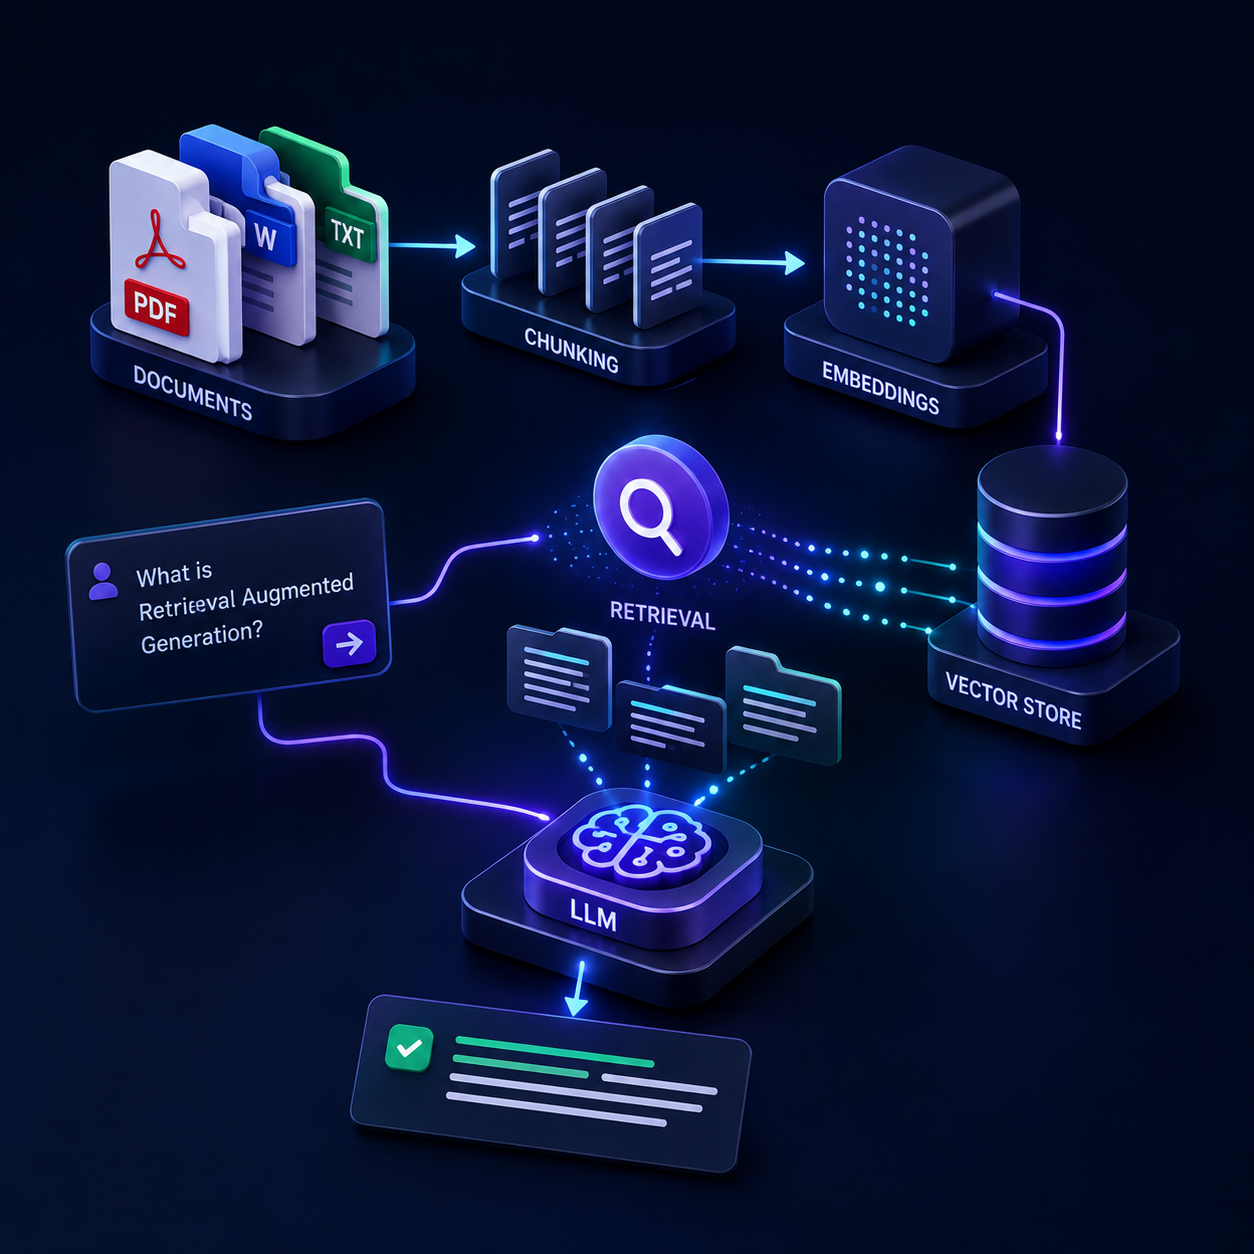
An end-to-end RAG application that lets users ask natural language questions over their own documents and receive context-grounded answers. Handles document ingestion, chunking with LangChain, embedding generation with Sentence Transformers, vector retrieval via FAISS, and LLM response generation — all through an interactive Streamlit interface.
status: available for full-time roles
Prateek Kumar
Software Engineer · GenAI · Data Engineering
I build Generative AI applications, data pipelines, and backend services — from production RAG systems to ETL workflows that keep data reliable at scale.
/about
From debugging circuits to building GenAI pipelines.
I studied Electronics & Communication Engineering at NIT Srinagar, but found myself drawn to software long before graduation. Late nights on LeetCode — 500+ DSA problems solved — and a final-year stint at Nexturn that turned into a full-time offer the day I graduated.
Today I work as a Data & GenAI Engineer, splitting my time between two disciplines most teams keep separate: data engineering (SQL, ETL pipelines, PySpark, Spark, Airflow) and applied Generative AI (LangChain, FAISS, RAG, OpenAI APIs). I also hold a Databricks Certified Generative AI Engineer Associate credential.
The problems I find most interesting sit at the intersection — making retrieval accurate enough to trust, building pipelines that don't drift silently, and writing APIs that hold up when users actually show up. I'd rather ship something reliable than something flashy.
Backend & Data
REST APIs, SQL, ETL pipelines with PySpark, Spark, and Airflow
Applied GenAI
RAG systems, vector search with FAISS, LLM application engineering
/experience
Where I've worked.
Data & GenAI Engineer
Nexturn · Bengaluru, India
Joined during my final year at NIT Srinagar; converted to full-time upon graduating in 2025.
- Designed and built a Retrieval-Augmented Generation (RAG) application using LangChain and FAISS for domain-specific question answering over unstructured documents.
- Engineered the full document processing pipeline end-to-end — chunking, embedding generation, vector indexing, and retrieval — for multi-turn conversational queries.
- Integrated OpenAI APIs and iteratively refined prompt templates through repeated testing to improve response relevance for domain-specific queries.
- Developed and optimized SQL queries using joins, aggregations, CTEs, and window functions for data transformation and business reporting.
- Built and debugged ETL pipelines to ingest, clean, and transform structured datasets using Spark.
/projects
Things I've built.
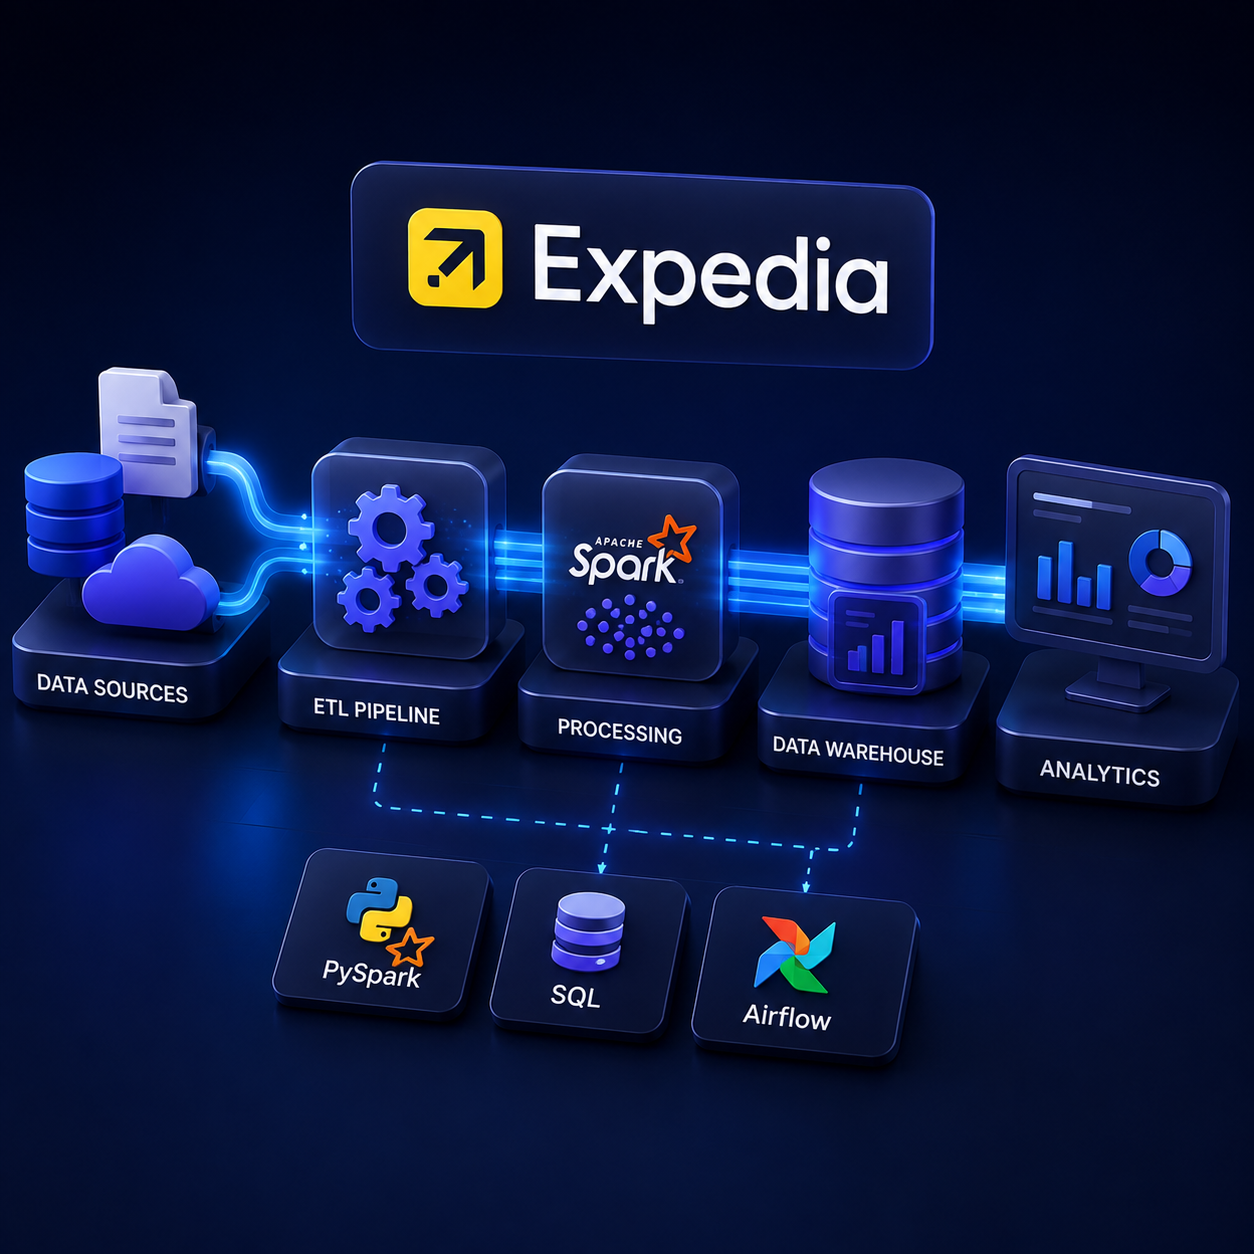
Expedia — Data Engineering Project
Onboarded to Expedia's data engineering team, gaining hands-on familiarity with the team's ETL pipelines and data workflows. Set up the development environment and explored the project's data processing architecture through knowledge-transfer sessions and technical documentation. Currently building practical experience with PySpark, Apache Spark, SQL, and Airflow.
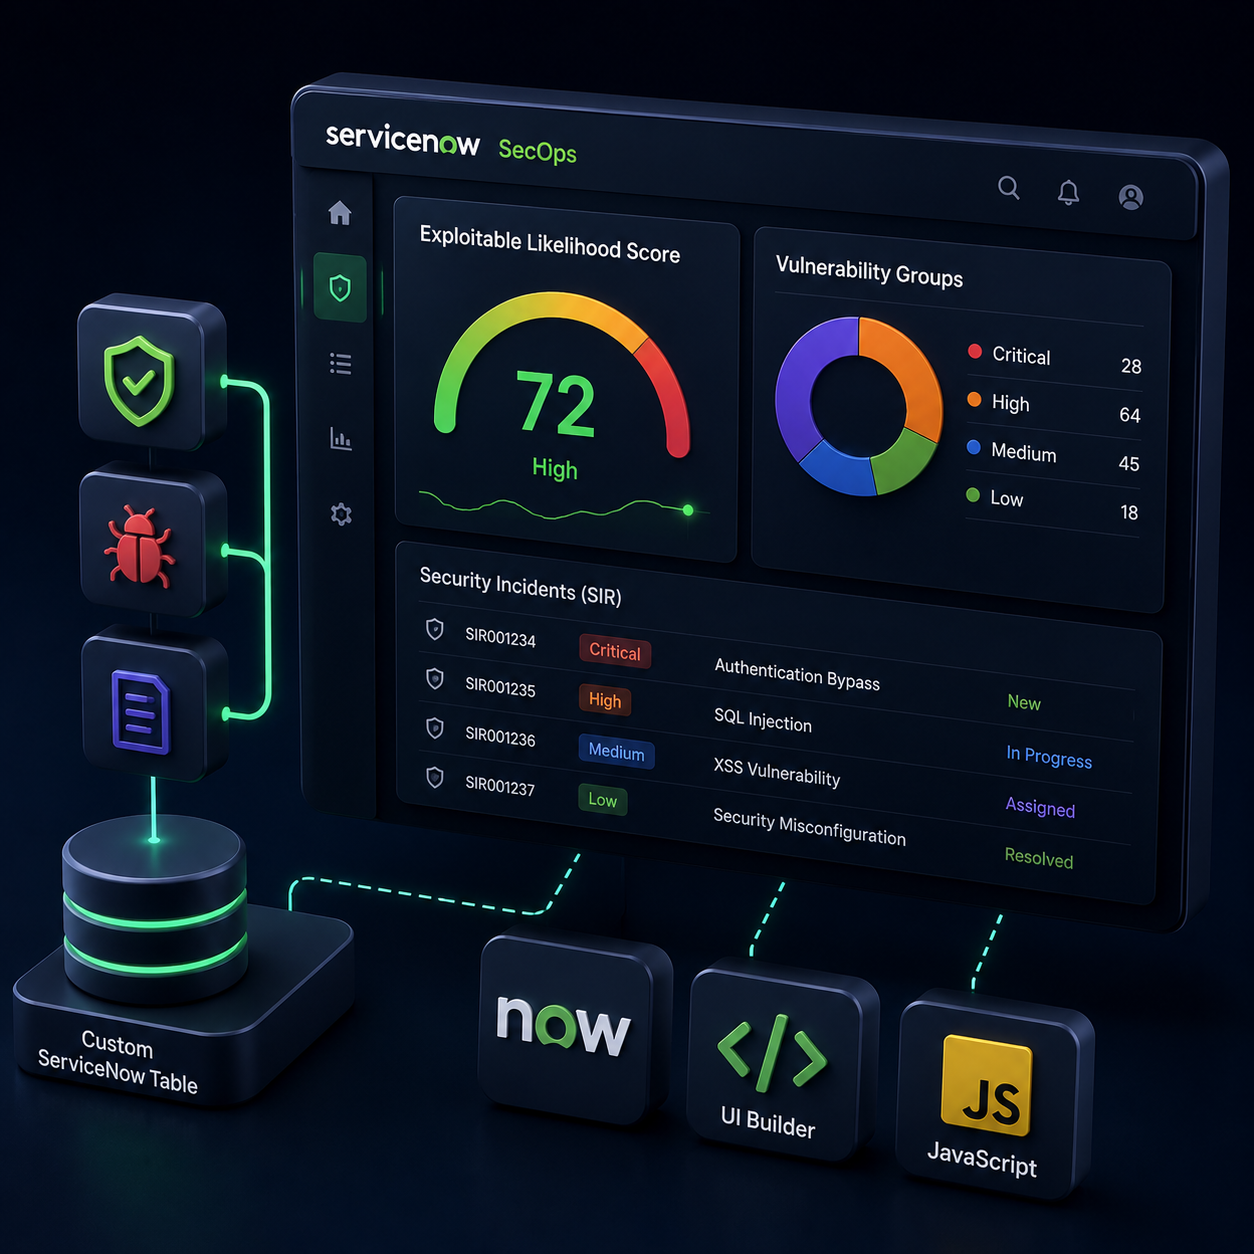
ServiceNow SecOps — Exploitable Likelihood Score Dashboard
A vulnerability-prioritization tool that computes an Exploitable Likelihood Score (ELS) from CVSS and threat data, backed by a custom ServiceNow table managing the underlying application data. Developed UI Builder pages to visualize ELS scores, vulnerability groupings, and Security Incident (SIR) records for security analysts.
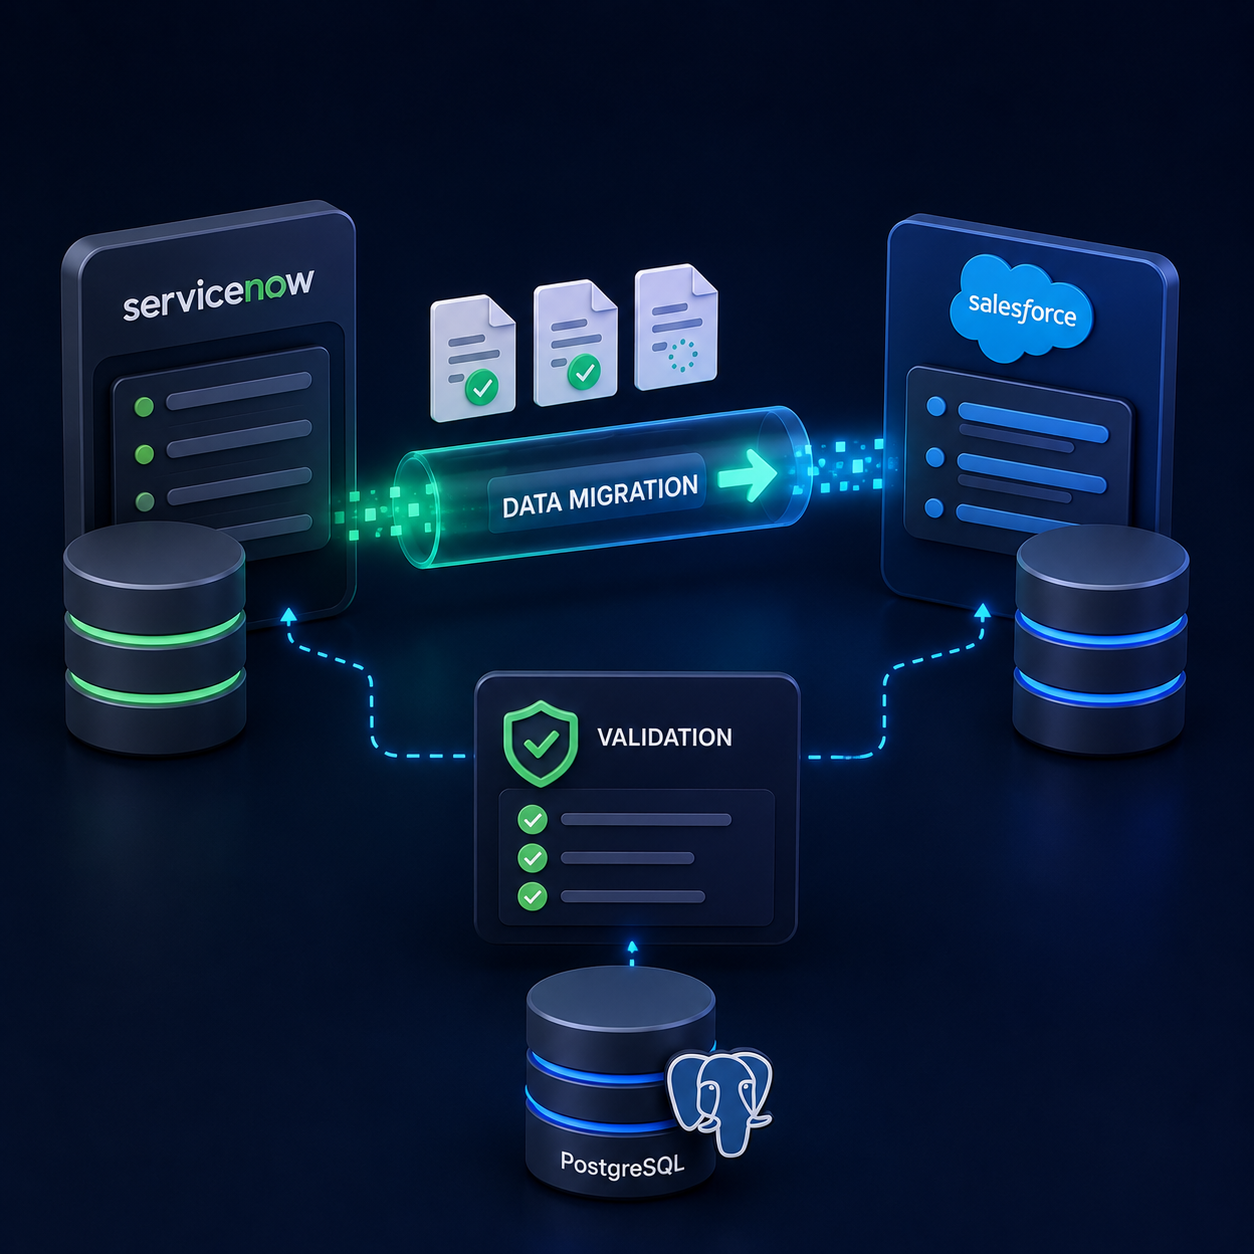
ITSM — ServiceNow to Salesforce Data Migration
Performed functional testing of the ServiceNow-to-Salesforce data migration workflow, validating field mappings, transformed data, and migration results. Compared source and target data across PostgreSQL tables to identify discrepancies and reported migration issues for resolution.
/skills
What I work with.
Languages
Backend & APIs
Data Engineering
Generative AI
Databases
Tools & Platforms
/achievements
Track record.
DSA problems solved on LeetCode
Year of production engineering experience
Projects shipped across GenAI, data, and SecOps domains
Databricks GenAI certification earned
Databricks Certified Generative AI Engineer Associate
Industry certification validating expertise in designing and building GenAI applications on the Databricks platform.
View Credential ↗National Institute of Technology (NIT), Srinagar
B.Tech in Electronics & Communication Engineering
Coursework: Data Structures & Algorithms, DBMS, Operating Systems, OOP
/why-hire-me
What I bring to a team.
Production GenAI experience
Not just prototypes — I've built and maintained a RAG pipeline end-to-end, including the ingestion, retrieval, and prompt-iteration cycle that makes LLM answers reliable in production.
Data engineering fundamentals
Hands-on with PySpark, Spark, and Airflow for ETL. I understand how data actually moves and breaks at scale, and I'm currently building on this through the Expedia data engineering project.
Strong CS fundamentals
500+ solved problems on LeetCode and a B.Tech grounding in DSA, DBMS, and OS — the foundations that make debugging and system design faster.
Certified in Generative AI
Databricks Certified Generative AI Engineer Associate — a signal that my GenAI knowledge goes beyond tutorials and includes production-grade design patterns.
Backend & API development
Comfortable writing REST APIs with Node.js and Express.js, optimizing SQL for reporting, and debugging data-intensive systems where correctness matters.
Fast ramp-up
Joined as an intern during my final year, shipped a production RAG system, and converted to a full-time engineer — I learn quickly and I ship.
/contact
Let's work together.
Open to full-time roles in software engineering, data engineering, and GenAI. I usually respond within 24–48 hours.